Python is used in data analysis primarily through the pandas library, which handles data too large, too messy, or too repetitive for Excel to manage cleanly — and it's what lets an analysis be automated and re-run rather than redone by hand every time new data arrives. It's not a replacement for SQL or Excel; it's the tool you reach for once those two hit real limits.
Why Python, Specifically
Excel struggles past a few hundred thousand rows and makes repeatable, auditable analysis difficult — a formula changed by hand in one cell doesn't show up in a change log the way a line of code does. SQL is excellent for pulling and aggregating data that already lives in a database, but weaker for more involved cleaning logic, statistical analysis, or connecting to non-database sources like APIs and files. Python fills exactly this gap.
What to Actually Focus On
For data analysis specifically (as distinct from general-purpose Python programming), the priority order is:
- pandas — DataFrames, filtering, grouping, merging, and handling missing data; this is 80% of practical day-to-day Python data work.
- Basic Python fundamentals — variables, loops, functions, and lists/dictionaries, enough to read and write pandas code comfortably, not deep software-engineering knowledge.
- matplotlib/seaborn — enough to visualize a distribution or trend quickly while exploring data, even though final polished dashboards usually move to Power BI instead.
- Jupyter notebooks — the standard environment for exploratory analysis, since they let you run and re-run small pieces of analysis interactively rather than an entire script at once.
What You Can Skip for Now
Object-oriented programming, web frameworks, and software-engineering-heavy topics like testing frameworks and packaging matter for software engineers, not analysts — useful eventually if you move toward data engineering, unnecessary to start doing real analyst work with Python.
A Realistic Use Case
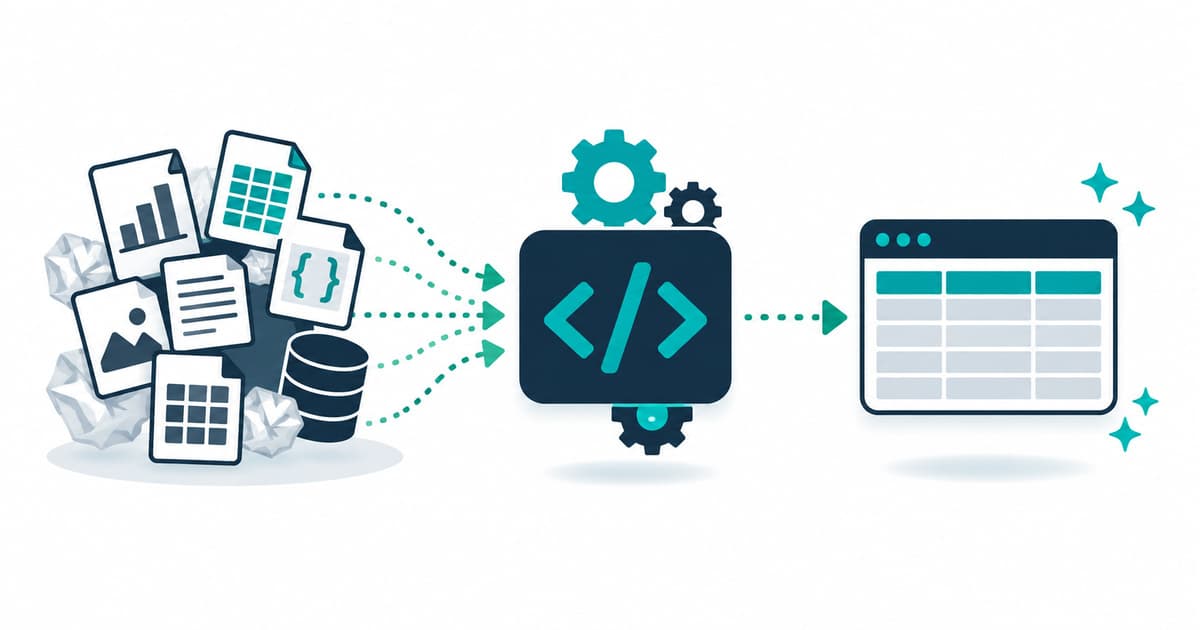
A common real scenario: three separate export files (different date formats, inconsistent column names, some duplicate rows) need to become one clean dataset ready for analysis. Doing this by hand in Excel every time it recurs wastes hours; a pandas script that loads, standardizes, deduplicates, and merges all three takes seconds to re-run once written — and this exact kind of messy-data-cleaning task is where Python earns its place in an analyst's toolkit fastest.
Where This Fits in the Bigger Picture
Python is the third step in most analysts' learning path, after Excel and SQL — not because it's less important, but because the fundamentals it builds on (thinking in rows/columns, writing filter and grouping logic) are easier to learn in simpler tools first. Our online Data Analytics course introduces Python for exactly the use cases described here — cleaning, merging, and analyzing real multi-source datasets — rather than teaching Python as a standalone programming course disconnected from actual analyst work.